
Bare metal NVIDIA GPUs, without running a data centre
A sovereign GPU cloud with bare metal access to the latest NVIDIA GPUs in dedicated AI data centre space. We take care of the networking, storage and round-the-clock operations, so your teams can focus on the work.
Compute
The NVIDIA GPUs your workloads need
Bare metal, built to NVIDIA reference architectures, with drivers ready to use.
 Coming soonNVIDIA Rubin is coming to the PrivateMind platform. Register your interest for early capacity.
| GPU | Architecture | Memory | Best for |
|---|---|---|---|
| B300 | Blackwell Ultra | 288 GB HBM3e | For the largest training runs and for serving reasoning models at scale. |
| B200 | Blackwell | 180 GB HBM3e | Training and high-throughput inference for frontier-scale open-weight models. |
| H200 | Hopper | 141 GB HBM3e | Extra memory for long-context inference and fine-tuning larger models. |
| H100 | Hopper | 80 GB HBM3 | The proven choice for training, fine-tuning and production inference. |
| RTX PRO 6000 | Blackwell | 96 GB GDDR7 | Cost-effective inference, fine-tuning and development workloads. |
| Alternate GPU models | On request. Tell us what your workload needs and we will match the hardware. | ||
GPU pricing is quoted per contract. Fractional GPUs, reserved terms and multi-pod clusters are available. See the pricing page or request a demo for a quote.
Capacity
Take exactly the capacity you need
Fractional nodes
Rent individual GPUs or MIG slices on a server we share out, each isolated from other tenants and allocated through the Control Plane.
Bare metal nodes
Whole HGX systems with direct access to the hardware and nothing between your workload and the GPUs.
Pods and clusters
Multiple pods across our data centres for large training and inference estates, with the build, cabling and operations handled by us.
Data centres and networking
AI data centre space around the world
We operate globally, so you can choose where your workloads run to help meet UK and EU GDPR and outsourcing requirements on where data is held. We design, build and run the network, so your engineers never think about switches or other tenants.
- Cooling
- Liquid or air cooled, depending on the hardware and density
- Design
- Built to NVIDIA reference architectures for compute, networking and storage
- Fabric
- Ethernet up to 800G, for low latency and high throughput
- Isolation
- Isolated by default, with public IPs, route tables, CIDR blocks, security groups and firewalls
Global connectivity
Connected to the markets your firm trades on
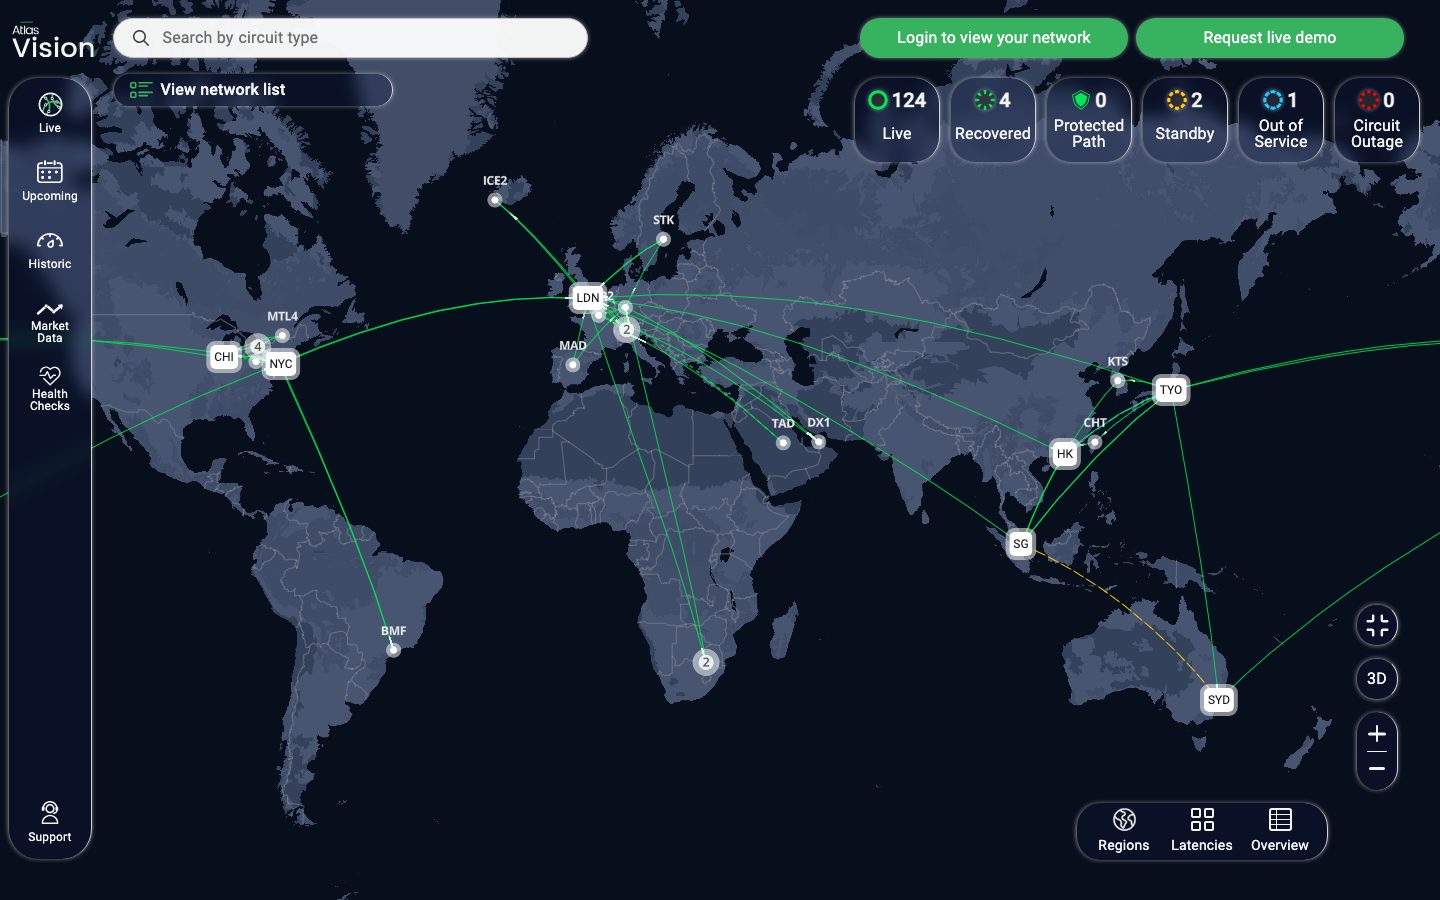
PrivateMind runs on the Options Technology network, which links financial centres around the world. AtlasVision shows every circuit and its health live.
Storage
Wherever the GPUs go, storage goes with them
Large volumes sit next to your compute, so data does not travel to reach the GPUs that need it.
 Whitepaper: KV cache offloading for long-context inferenceRequest the whitepaper
- Block storage
- Persistent volumes for operating systems, databases and working datasets, attached to GPU and CPU hosts.
- Object storage
- Buckets for datasets, checkpoints and model weights, available to training jobs, workspaces and inference endpoints.
- High-performance object storage
- High-throughput storage built with VAST and Everpure to keep large GPU clusters fed during training.
Managed services
What we run for you
The data centre and everything in it is our responsibility. More can be added on request.
About AtlasVision- A dedicated dashboard for your estate
- 24/7 alerting and NOC operations
- Regular utilisation reports
- Network design and tuning for bandwidth and throughput
- Advice on sizing as your usage grows
- EDR across hosts and containers
- Log integration with your SIEM
- Confidential computing for sensitive workloads
- Dedicated WAN circuits into your offices and data centres
- Connectivity to global exchanges, visible in AtlasVision
Which NVIDIA GPUs can we get?
Bare metal access to NVIDIA B300, B200, H200, H100 and RTX PRO 6000, with alternate GPU models available on request. NVIDIA Rubin is coming to the platform, and you can register your interest for early capacity.
Can we rent part of a GPU, or do we need whole nodes?
Take exactly the capacity you need. Rent individual GPUs or MIG slices on a server we share out, each isolated from other tenants, whole bare metal HGX nodes with direct access to the hardware, or multiple pods across our data centres for large training and inference estates.
Is the network isolated?
Yes, isolated by default, with public IPs, route tables, CIDR blocks, security groups and firewalls, and Ethernet up to 800G. We design, build and run the network, so your engineers never think about switches or other tenants.
How is GPU capacity billed?
GPU pricing is quoted per contract. Fractional GPUs, reserved terms and multi-pod clusters are available. See the pricing page or request a demo for a quote.
Request a demo of dedicated GPUs for your firm
Tell us what you want to run and where it needs to live. We will come back with the hardware, storage and network design that fits.